Build a Jev-Style Decision Model from Scratch
An LLM that returns calibrated probabilities, not text: architecture, PyTorch build, training, serving
All 23 lectures are free to watch here and on YouTube. The $10 is for the course materials: the notebooks, code and trained checkpoints used in the lectures.
01
What changes after this course
- ●Instead of sending every routing or triage step to an expensive LLM, you put a decision model in front of it, and know when a small classifier is the better choice
- ●Instead of trusting a 90% confidence, you check calibration and decide which cases go to a person
- ●Instead of only calling models through an API, you build and measure one yourself
02
Why it matters now
Decision models are new: Jev shipped in September 2026 and open models such as Kev and MoJev reproduce the idea. A decision model answers without generating text, so a routing step skips the output tokens and can run on a much smaller model. We expect many LLM pipelines to add one in front of the expensive model to cut token cost. Once they do, the probability is the part that fails quietly. In this course, training longer looked better on familiar questions while the share of answers wrong at 90% confidence or more on unseen intents rose from 2.7% to 9.7%. Knowing how to catch that before it reaches users is the skill this course is about.
03
What you leave with
- ✓Five notebooks that run end to end: the picture, the build, training, calibration and serving
- ✓Trained checkpoints, so you can skip training and start measuring
- ✓Your own reliability diagrams, ECE, Brier and confident-error numbers, measured on public data (BANKING77, CLINC150)
- ✓A served model behind the same API shape as Jev that sends low-confidence cases to a person and logs every case
04
Skills you'll build
- →Explain how a decision model like Kev turns a message and a list of options into one probability per option (Jev’s internals are not public; the course builds the inferred design)
- →Build that design yourself in PyTorch on a 0.6B Qwen base and train it on yes/no, choice and ordered-score questions
- →Tell whether a model’s 90% actually means 90%, and largely correct it when it does not
Inside the course
Screens from the lectures. The notebooks and code on screen are the ones you download; Kev and the TypeSafe SDK are open third-party tools.
Terminal: Kev served locally
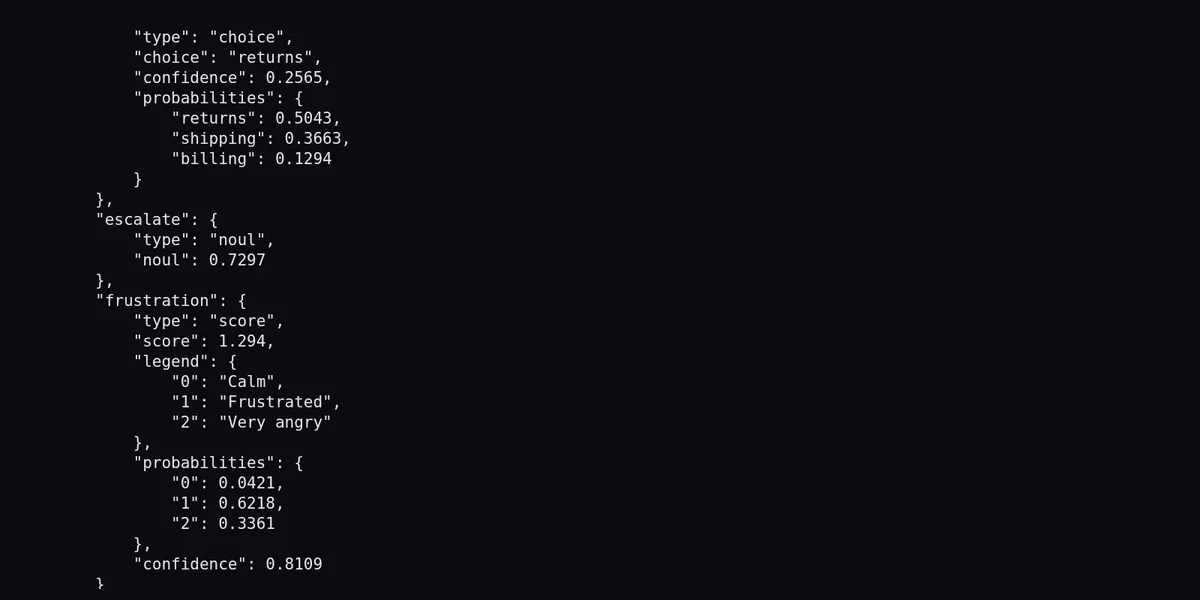
One ticket in, three distributions out
The course opens on the finished thing: an open Jev-style model answering a support ticket. Which team: returns 0.50, shipping 0.37, billing 0.13. Escalate: 0.73. Frustration: expected level 1.29. No text is generated.
▶ Lecture 1.1 · reference demo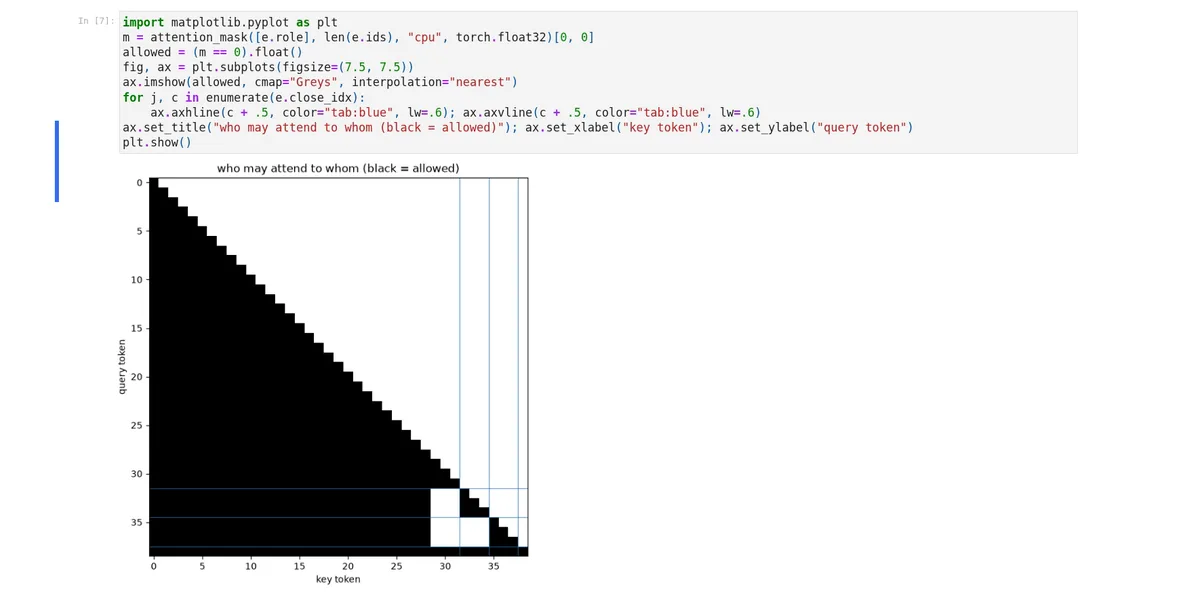
01_the_picture.ipynb
The mask, drawn from a real record
Causal attention plus two rules: an option sees the context and itself, never another option, and the decide token sees everything. The white squares in the bottom corner are where options are cut off from each other.
▶ Lecture 2.3 · the mask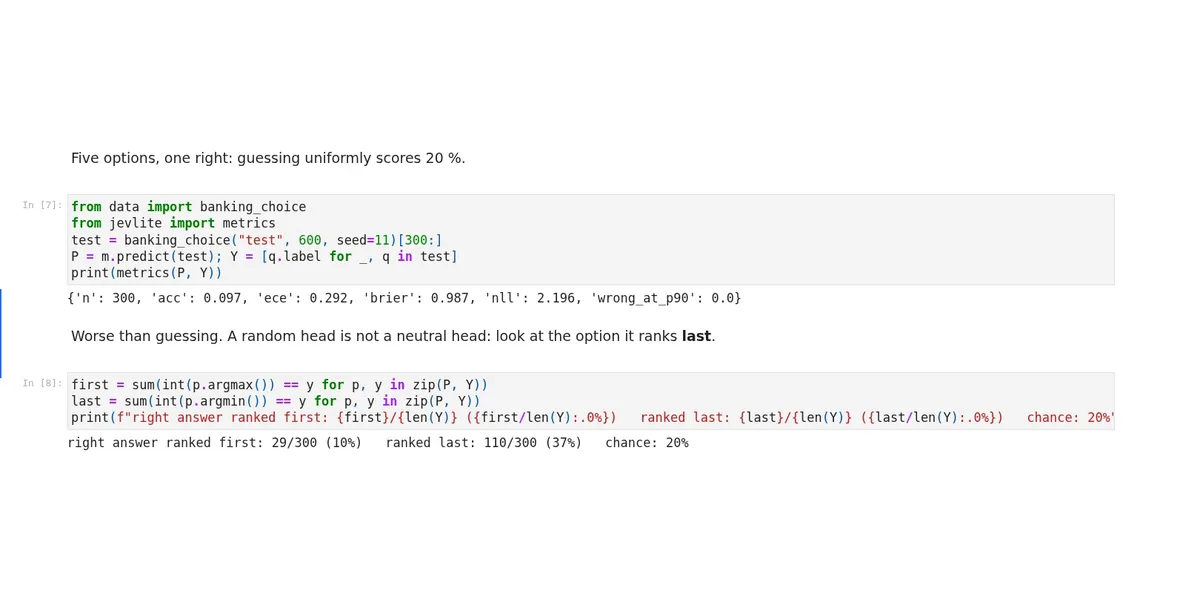
02_building_it.ipynb
An untrained head is worse than guessing
Five options, so guessing scores 20%. The random pointer head scores 9.7% and ranks the right answer last 110 times out of 300. You see why before you train it.
▶ Lecture 3.3 · what an untrained head does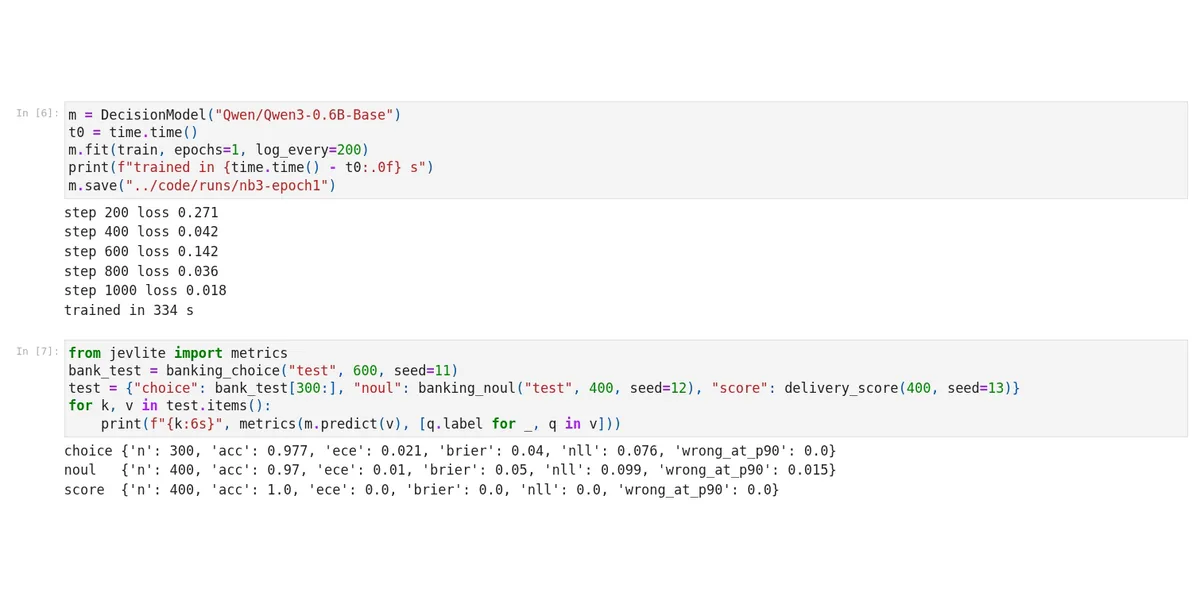
03_training.ipynb
One LoRA epoch in 334 seconds
Qwen3-0.6B-Base, LoRA and the pointer head, trained on one A100. Test accuracy: choice 97.7%, yes/no 97.0%, score 100%. The score task is generated and too easy, and the lecture says so.
▶ Lecture 4.2 · training one epoch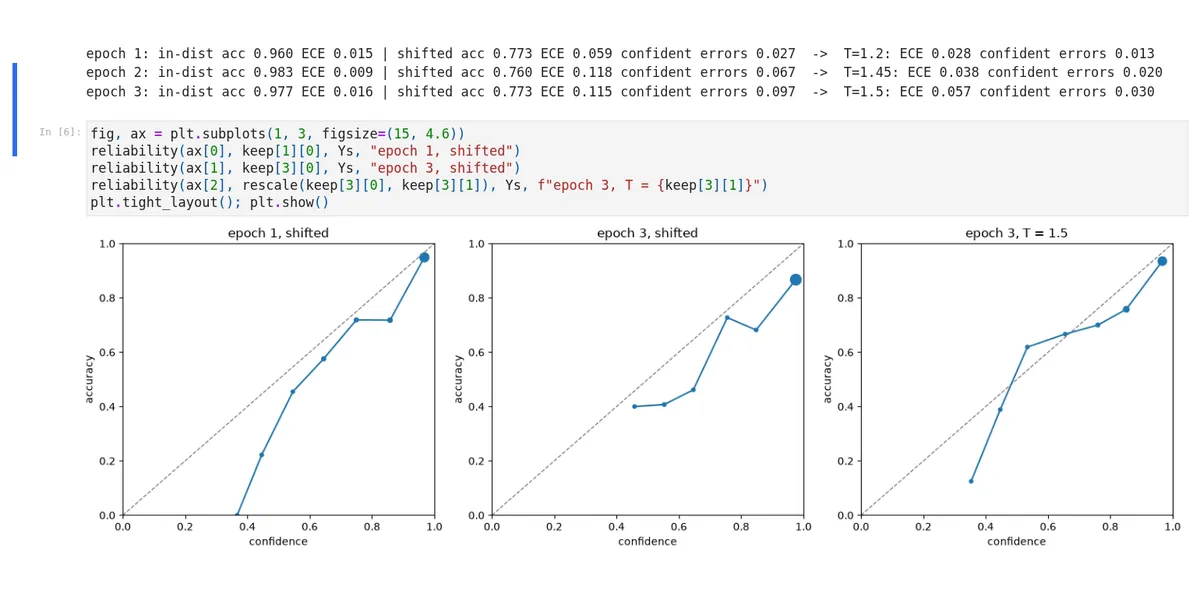
04_calibration.ipynb
Training longer made it overconfident
On intents the model never saw, answers that were wrong at 90% confidence or more rose from 2.7% after one epoch to 9.7% after three. One temperature, T = 1.5, brings it down to 3.0%, still above the one-epoch model's 2.7%.
▶ Lecture 5.3 · train longer and temperature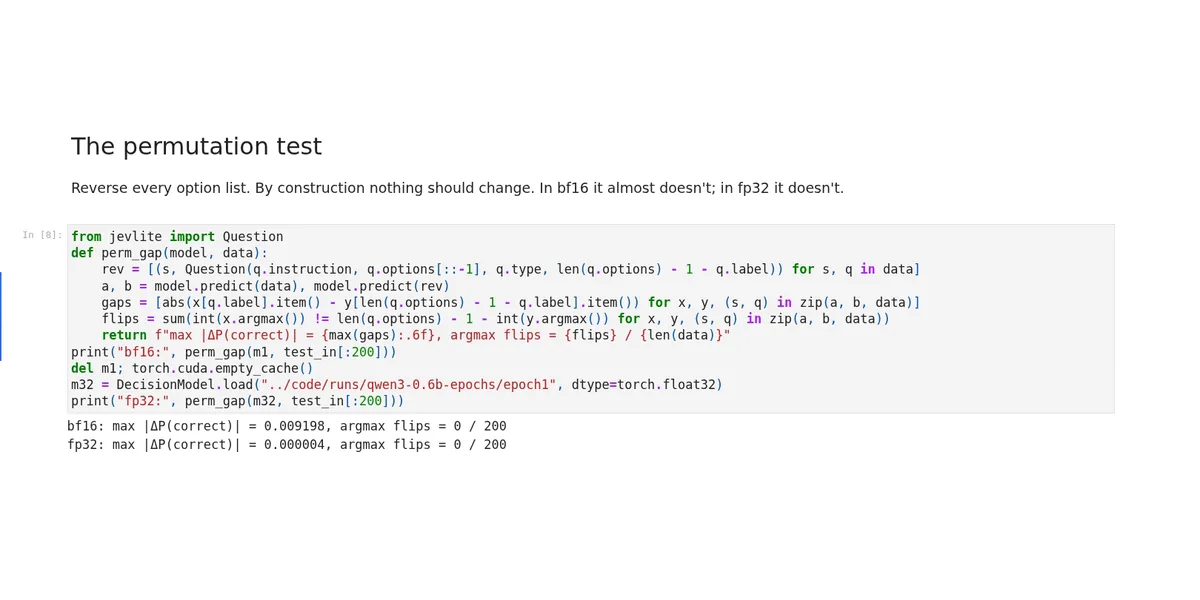
04_calibration.ipynb
Option order does not change the answer
Reverse every option list. In bf16 the probability of the right answer moves by at most 0.009; in fp32 by 0.000004. Answers flipped: 0 of 200.
▶ Lecture 5.4 · the permutation test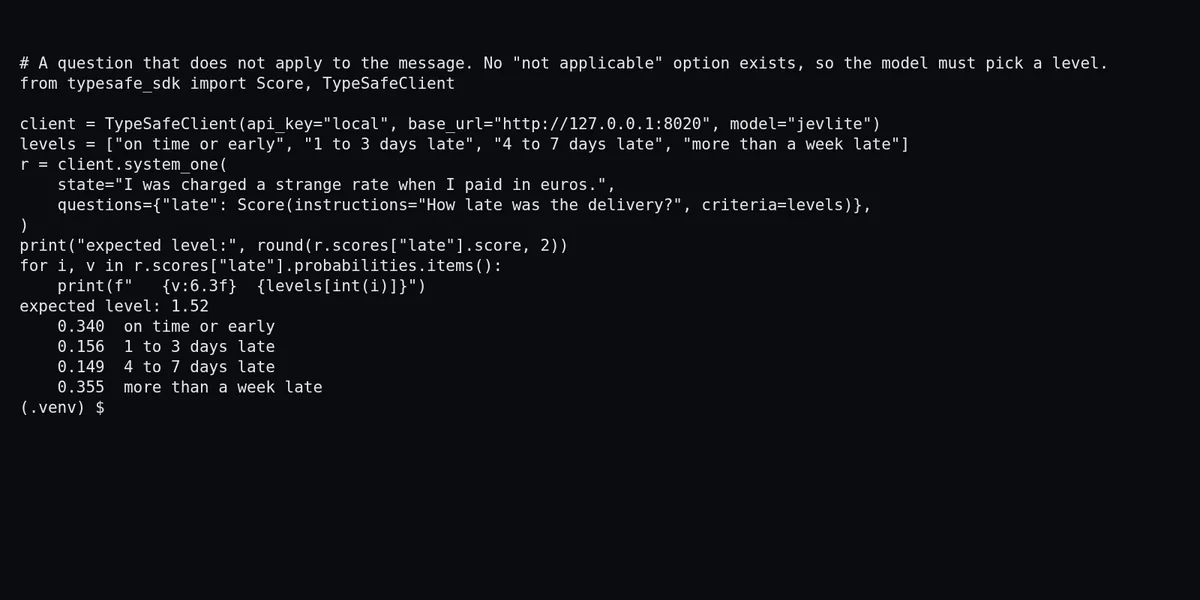
code/not_applicable.py → code/serve.py (official TypeSafe SDK)
Your model behind the same API
The model you trained, served locally and called with the official SDK. Here the question does not fit the message and there is no "not applicable" option, so the answer spreads: 0.340, 0.156, 0.149, 0.355.
▶ Lecture 6.2 · serve your model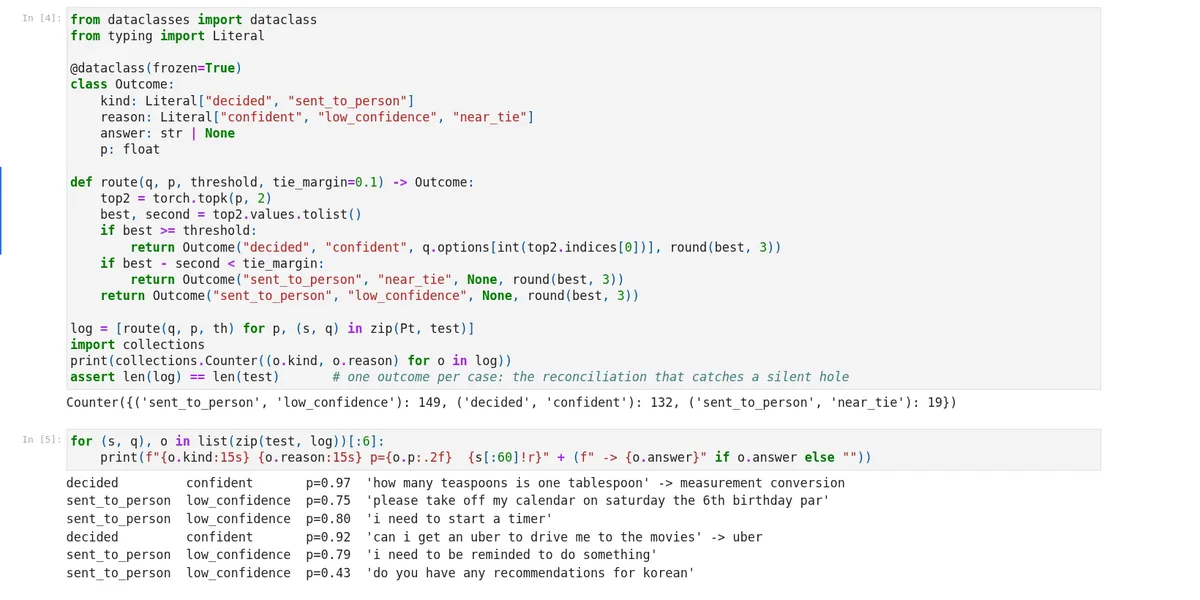
05_shipping.ipynb
Decide, or hand it to a person
The threshold is picked on dev and reported on test. Of 300 test cases, 132 were decided automatically and 168 went to a person with the reason attached. Every case gets exactly one outcome.
▶ Lecture 7.1 · decide or hand to a personWhat you'll learn
- ✓Explain how a decision model returns a probability distribution over supplied options without generating text
- ✓Implement delimiters, an option-isolating attention mask, shared position ids and a pointer head in PyTorch
- ✓Train yes/no, choice and ordered-score questions with LoRA and one cross-entropy loss
- ✓Measure calibration (reliability diagrams, ECE, Brier, confident errors) and largely correct overconfidence with temperature scaling
- ✓Verify option-order invariance with a permutation test
- ✓Serve a model behind a SystemOne-compatible API and route low-confidence cases to people
About this course
Jev, released by TypeSafe in September 2026, answers questions without writing a word: you send a message and typed questions, and it returns a probability for every option you gave it. Open models such as Kev and MoJev reproduce the idea. This course builds one from scratch, small enough to read end to end, and then measures whether its probabilities deserve trust.
We start by running Kev locally and making the honest case for and against decision models, using measurements from real benchmarks: when a small trained classifier is the better tool, and when a decision model earns its place. Then we build the design in PyTorch on a 0.6-billion-parameter Qwen base: borrowed special tokens as delimiters, an attention mask that keeps options from seeing each other, shared position ids that make option order irrelevant, and a pointer head that scores each option against a decide token. We train it with LoRA on public data (BANKING77, CC-BY-4.0) plus generated data, for three question types: yes/no, choice and ordered score.
Then the part most tutorials skip. We measure calibration with reliability diagrams, ECE, Brier score and confident-error rates; show that training longer raised the share of answers that were wrong at 90% confidence or more, on unseen intents, from 2.7% to 9.7% while in-distribution numbers looked better; largely correct it with a single temperature (back to 3.0%, though the one-epoch model stays better calibrated); and verify option-order invariance in float32. Finally we serve the model behind the same API shape as Jev and Kev, call it with the official TypeSafe SDK, and use its probabilities to route work between automatic decisions and people, with every case logged.
This course is not affiliated with or endorsed by TypeSafe AI; "Jev" names the model the course explains. Jev's internals are not public: the course builds the inferred design that open models follow, and says so. Every number we measure comes from notebooks you can run; figures from TypeSafe, Kev and published benchmarks are labelled with their source.
Datasets: BANKING77 (PolyAI, CC BY 4.0) and CLINC150 (Clinc, CC BY 3.0), used with attribution; question formats and splits are ours.
Curriculum8 sections · 23 lectures · 1h 58m
Section 0. Welcome
FreeSection 1. Reference Demonstration
FreeSection 2. Architecture Analysis
FreeSection 3. Implementation
FreeSection 4. Training
FreeSection 5. Calibration and Evaluation
FreeSection 6. Production Comparison and Serving
FreeSection 7. Deployment
FreeRequirements
- · Python 3.12 and comfort reading Python code
- · Basic PyTorch (tensors, nn.Module, a training loop)
- · An NVIDIA GPU with bfloat16 support (Ampere or newer). The lectures use one A100; trained checkpoints are included, so only notebook 3 trains (334 s on an A100)
Who this is for
- · ML engineers who route, classify or triage with LLMs and want calibrated probabilities instead of text
- · Developers evaluating Jev, Kev or similar decision models who want to know how they work and where they fail
- · Anyone who wants to build and measure a model rather than call an API
Read alongside the course
The voice-over is synthesized with a text-to-speech model. The scripts were drafted with AI assistance and reviewed by the instructor; the code and notebooks were designed by the instructor and built with AI assistance. Every number we measure comes from the notebooks you can run, and figures from other sources are labelled.