Paper of the Week
Every week, we hand-pick the papers that matter and review them in depth — each issue ships with a reproducible experiment.
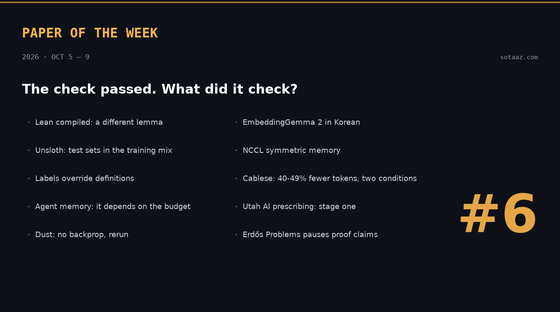
Paper of the Week #6 — The Check Passed. What Did It Check?
This week: a Lean proof that does not match the paper it formalizes, a decision-model table whose test sets are in its training mix, labels that override definitions, memory that wins or loses depending on how much the model reads, NCCL symmetric memory gains that depend on payload size and GPU, a 40-49% token cut that needs lowercase and thinking off, and an AI prescribing pilot whose first phase has two physicians check every prescription.
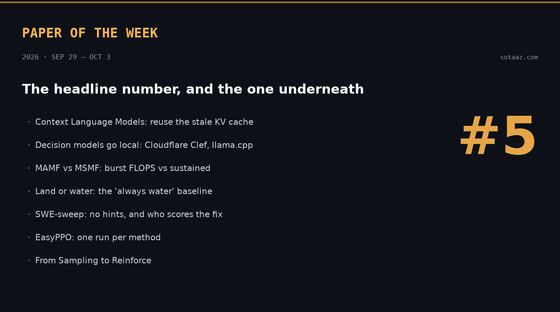
Paper of the Week #5 — Stale Caches, Burst FLOPS and Decision Models Going Local
This week: Context Language Models reuse a stale KV cache after editing their own context, two ways to run Jev-style decision models yourself, sustained GPU FLOPS 8 to 17 points below the burst number on four NVIDIA cards, and a map eval where always answering water scores 66%.
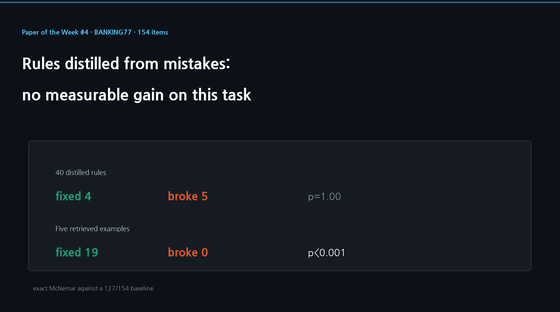
Paper of the Week #4 — A Memory of Procedures, or a Memory of Examples?
Designer-RSI grows a natural-language skill bank from user traffic and lifts execution success from 72.7% to 99.3% with no weight updates. I built the narrow version on a task with human labels: 40 rules distilled from the model's own mistakes fixed 4 items and broke 5. Retrieving five raw examples fixed 19 and broke none.
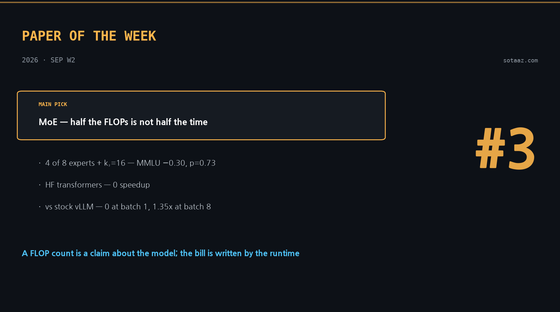
Paper of the Week #3 — Half the FLOPs Is Not Half the Time
One integer halves a fine-grained MoE's expert compute (arXiv 2609.04575) and its Table 5 replicates on one A100 to within a point. The paper never reports time, so I measured it: nothing in HF transformers, nothing at batch 1 in the vLLM you run today, 1.35x at batch 8. Plus the OLMoE control and the iso-cost harness control promised in issue #2.
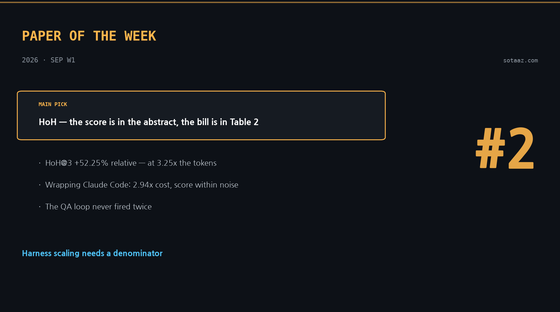
Paper of the Week #2 — The Score Is in the Abstract, the Bill Is in Table 2
I rebuilt HoH's Planner→Developer→QA loop (arXiv 2609.01481) around Claude Code on 8 hidden-test tasks: the score gap stayed inside rerun noise while tokens tripled, 58k vs 177k. HoH's own Table 2 reports 3.25x. Plus the matched-loss control promised in issue #1, graded.
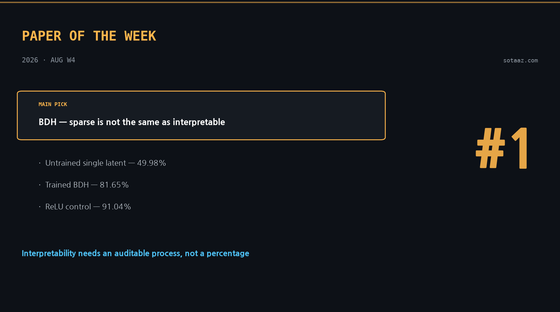
Paper of the Week #1 — Sparse Is Not the Same as Interpretable
I trained BDH and counted more than 4.8 billion activations across three controls. Training moved its single-latent sparsity from 49.98% to 81.65%, but a similar-budget ReLU baseline reached 91.04%. Sparsity is real; by itself, it is not evidence of interpretability.
A new issue lands every week. Want a paper covered? Tell us.