Latent Diffusion to SANA from Scratch
Stable Diffusion, VAE and CFG, Diffusion Transformers, PixArt-α and SANA, each implemented in PyTorch
01
What changes after this course
- ●Instead of reading each text-to-image paper as a new system, you tell which part changed from the model before it
- ●Instead of only calling a Stable Diffusion-style model, you modify its conditioning, guidance and backbone
- ●Instead of finding a licence limit after deployment, you pick conditioning components with their licences checked
02
Why it matters now
Text-to-image moved from U-Nets to Transformers and, in 2024, to efficient designs such as PixArt-α and SANA. This course implements them in order and compares each model with the previous one, so you see what each paper actually changed.
03
What you leave with
- ✓Four notebooks: LDM, DiT, PixArt and SANA
- ✓Models you trained on MNIST latents, yours to keep
- ✓A LICENSES.md that flags the CLIP weights as out of scope for deployed use and points to the permissive T5 path
04
Skills you'll build
- →Build a two-stage latent diffusion pipeline with a VAE and text conditioning through cross-attention
- →Implement classifier-free guidance for training and sampling
- →Build a DiT with adaLN-Zero, reproduce PixArt-α’s block and SANA’s linear attention with rectified flow
Inside the course
Screens from the lectures. Each architecture is built and run at MNIST scale in the four notebooks you download; the pretrained VAE and text encoders are third-party open models.
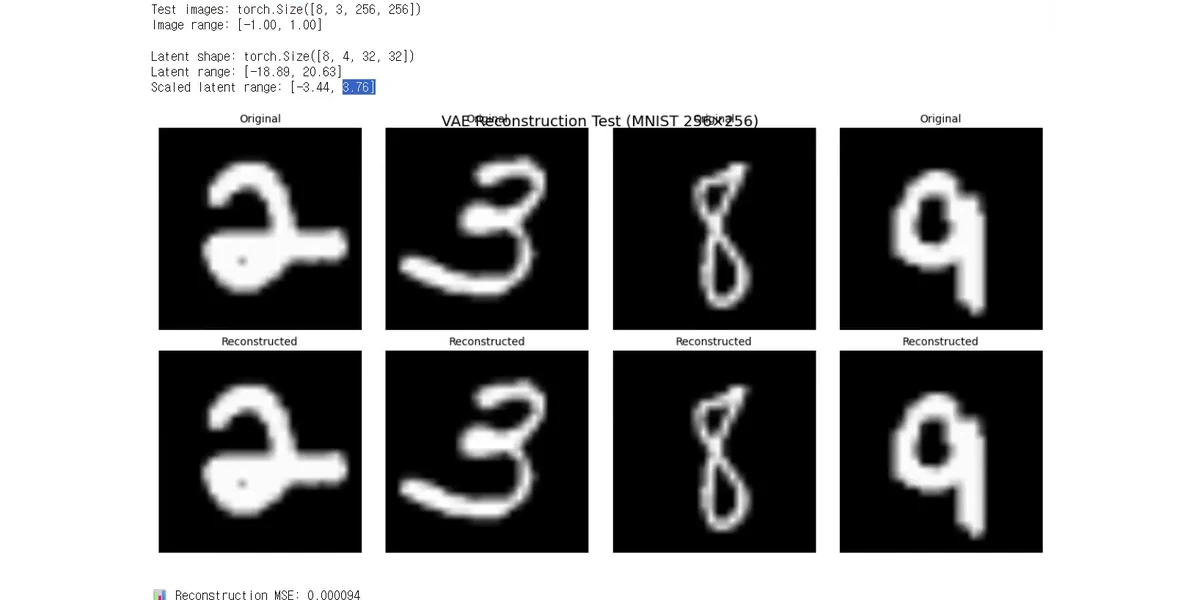
notebooks/03_LDM.ipynb
Into the latent space and back
A batch of 256 by 256 images goes through the VAE encoder to a 4 by 32 by 32 latent and back out. The reconstructions sit under the originals, and the printed reconstruction MSE is 0.000094.
Lecture 1.5 · Unconditional LDM implementation
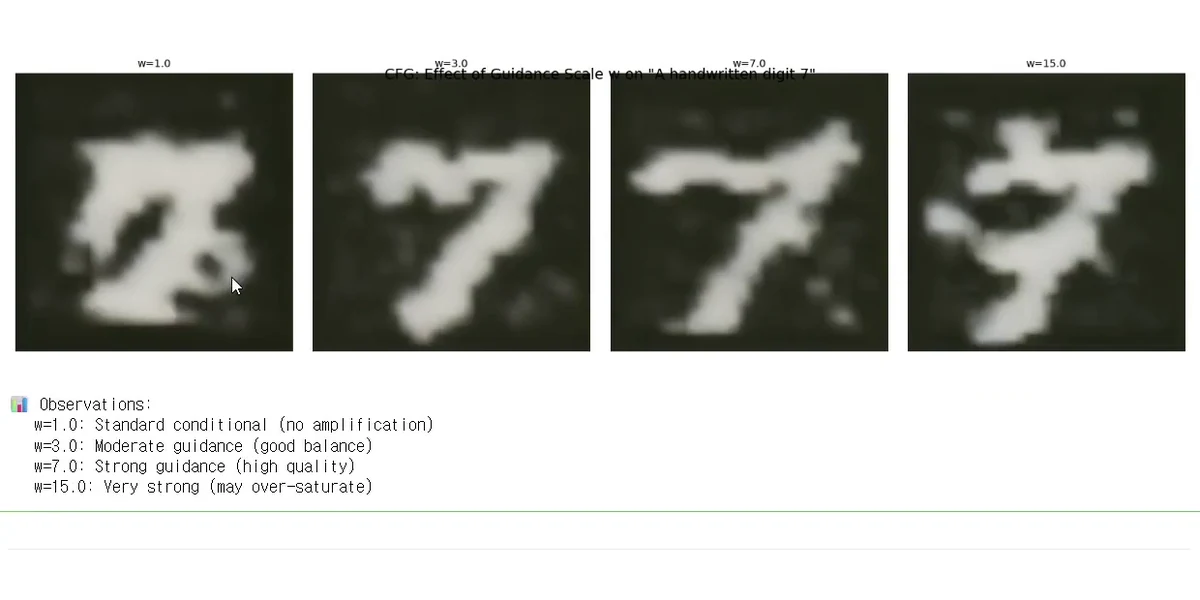
notebooks/03_LDM.ipynb
One prompt, four guidance scales
The same prompt, "A handwritten digit 7", sampled with classifier-free guidance at w = 1.0, 3.0, 7.0 and 15.0. At 1.0 the digit is hard to read, 3.0 and 7.0 give a clear 7, and 15.0 starts to break apart.
Lecture 1.9 · Sampling implementation
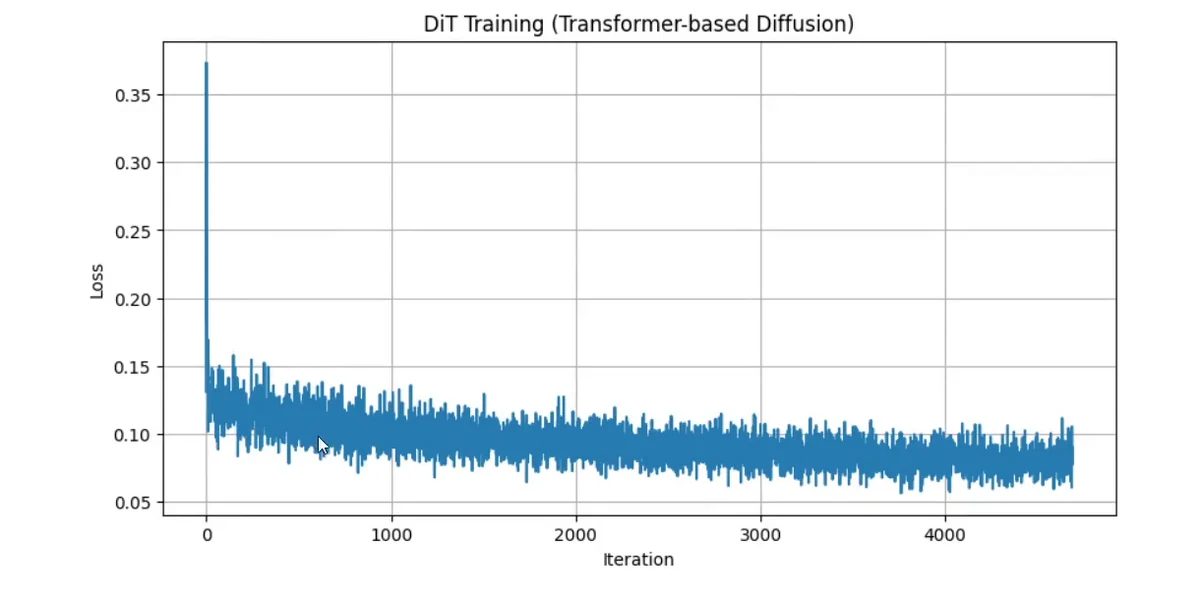
notebooks/04_dit.ipynb
The U-Net swapped for a Transformer, trained
The Diffusion Transformer you write, trained in latent space. The loss drops from a first spike near 0.35 into a noisy band between 0.10 and 0.15 almost at once, then creeps down below 0.10 by 4000 iterations.
Lecture 2.3 · DiT training and sampling
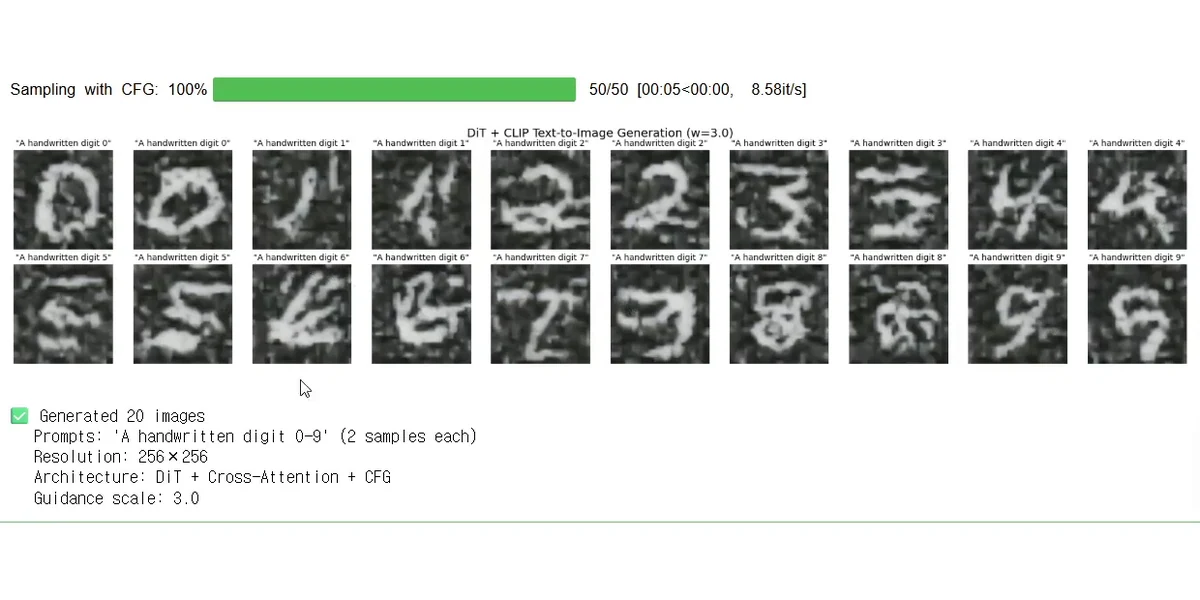
notebooks/04_dit.ipynb
Text in, digits out, with a DiT
The DiT gets cross-attention to CLIP text embeddings. Twenty images from prompts "A handwritten digit 0-9", two each, at guidance scale 3.0. About half are readable; the 5s, 7s and 8s are not yet.
Lecture 2.5 · CLIP DiT sampling
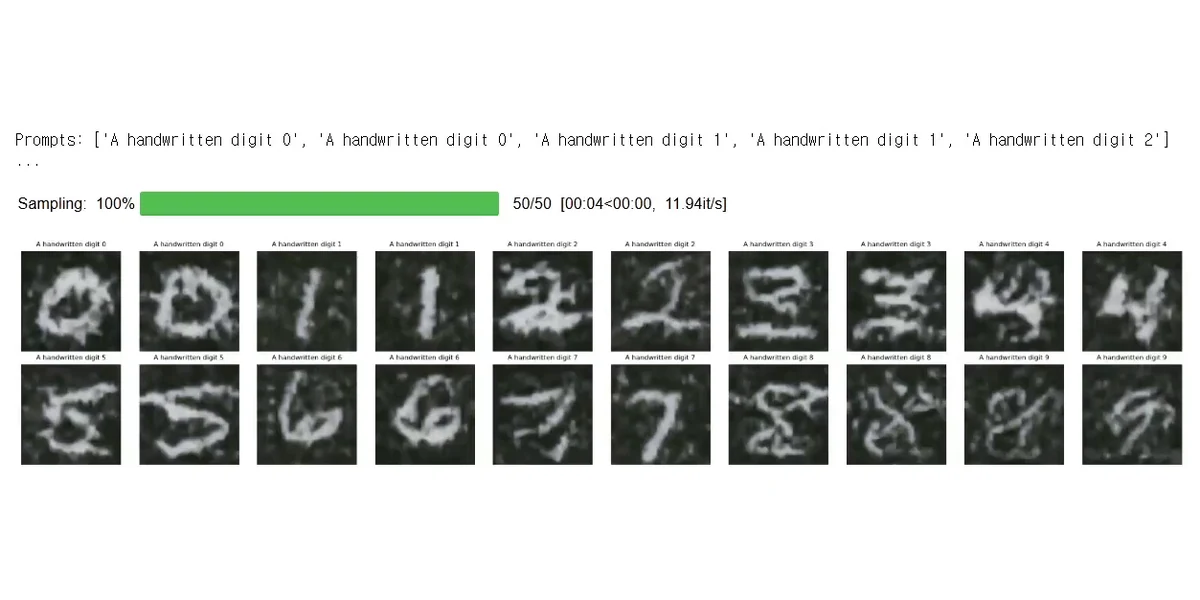
notebooks/05_pixart.ipynb
PixArt-α, scaled down to run on MNIST
A PixArt-α style model conditioned on text, sampled for 50 steps over the prompts "A handwritten digit 0" to "9", two images each. The results are blurry at this scale and you see them as they come out.
Lecture 3.2 · PixArt training and sampling
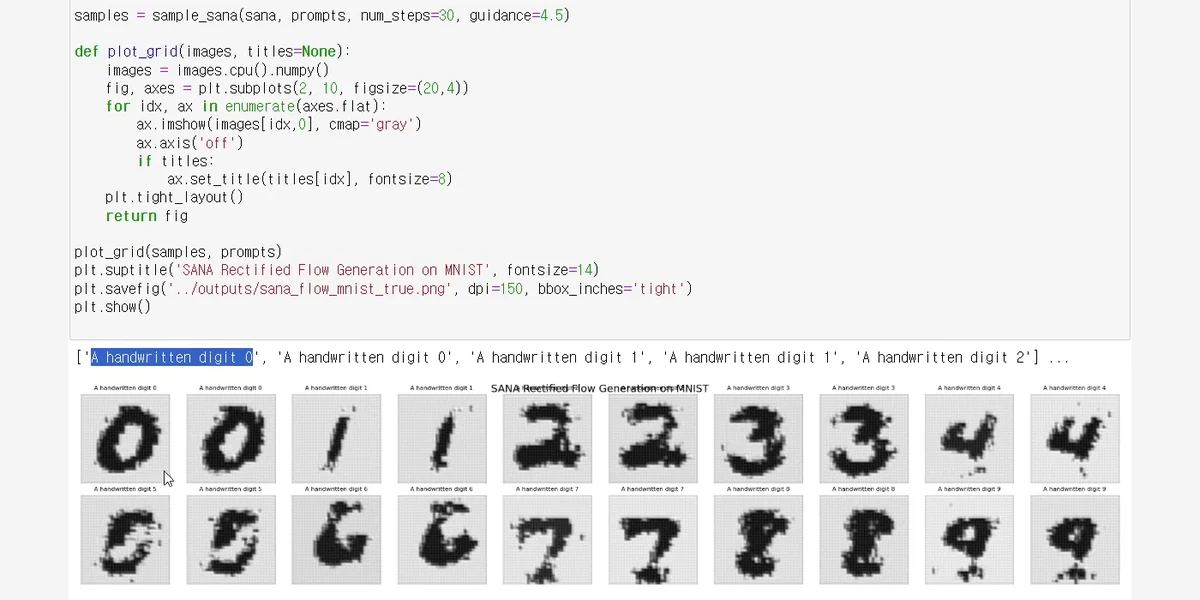
notebooks/06_sana.ipynb
SANA's rectified flow in 30 steps
The last model of the course: a small SANA with linear attention and a rectified-flow sampler. Thirty steps at guidance 4.5 give two images per prompt, "A handwritten digit 0" to "9".
Lecture 4.2 · SANA implementation
What you'll learn
- ✓Explain why latent diffusion is faster and how the VAE, scaling factor and two-stage training fit together
- ✓Implement text-conditional latent diffusion with CLIP embeddings and cross-attention
- ✓Implement classifier-free guidance for training (condition dropout) and sampling (guidance scale)
- ✓Build a Diffusion Transformer with adaLN-Zero conditioning and train it with class and CLIP conditions
- ✓Understand PixArt-α's multimodal DiT block and reproduce it on MNIST latents
- ✓Implement SANA's linear attention block and rectified-flow (flow matching) training and few-step sampling
About this course
This course picks up where DDPM ends and follows the field to the models that dominate today. We move diffusion into a compressed latent space with a VAE (the idea behind Stable Diffusion), add text conditioning with CLIP and classifier-free guidance, replace the U-Net with a Transformer (DiT), and finish with the efficient architectures of 2024: PixArt-α and SANA with linear attention and rectified flow.
Each chapter follows the same recipe: read the paper, derive the key equations in plain language, implement the model in PyTorch, train it on MNIST latents, and look at the samples. You will implement a two-stage latent pipeline, a text-conditional U-Net with cross-attention, CFG training with condition dropout and CFG sampling, DiT blocks with adaLN-Zero, CLIP-conditioned DiT, the multimodal DiT of PixArt, and SANA's linear attention with a rectified-flow scheduler.
Every lecture shows the notebook on screen while the narration explains each cell. Trade-offs and failure modes are discussed openly, and every model is compared with the one before it so you understand what each paper actually changed.
Prerequisite: DDPM and DDIM basics — from our course *DDPM and DDIM from Scratch* or equivalent.
**Licensing.** The models you train here are yours, but two pretrained components are downloaded and frozen: `stabilityai/sd-vae-ft-mse` (MIT — no obligations beyond attribution) and `openai/clip-vit-base-patch32`, whose weights carry no declared licence and whose model card states that any deployed use, commercial or not, is out of scope. `Resources/LICENSES.md` sets this out and points at the fully permissive T5 conditioning path that sessions 5 and 6 already use.
Curriculum5 sections · 23 lectures · 2h 37m
Section 0. Welcome
Free previewSection 1. Latent Diffusion and Stable Diffusion
Free preview- ▶section 1 intro0:18
- ▶Latent diffusion intro3:48
- 🔒How latent diffusion works5:54
- 🔒Two stage training6:06
- 🔒VAE11:24
- 🔒Unconditional LDM implementation12:18
- 🔒Conditional LDM implementation11:06
- 🔒Classifier free guidance4:36
- 🔒CFG training implementation8:12
- 🔒Sampling implementation9:06
Section 2. Diffusion Transformers
- 🔒section 2 intro0:18
- 🔒DiT vs UNet4:00
- 🔒DiT implementation11:06
- 🔒DiT training and sampling4:18
- 🔒CLIP conditioned DiT8:42
- 🔒CLIP DiT sampling5:42
Section 3. PixArt-alpha
- 🔒section 3 intro0:18
- 🔒PixArt and MMDiT12:36
- 🔒PixArt training and sampling5:36
Section 4. SANA
- 🔒section 4 intro0:18
- 🔒SANA and rectified flow10:36
- 🔒SANA implementation18:48
Requirements
- · A computer with Python 3.10+ (a free Google Colab account is enough for most sessions)
- · Comfort reading Python code; you do not need to be an expert
- · Understanding of DDPM (forward/reverse process, noise-prediction loss) and DDIM
- · Basic PyTorch and the diffusers library basics
Who this is for
- · Engineers who fine-tune or deploy Stable Diffusion and want to understand its internals
- · Researchers and students following the DiT / PixArt / SANA line of work
- · Graduates of DDPM and DDIM from Scratch who want the modern models
- · Anyone building text-to-image systems who needs more than an API call
Read alongside the course
The voice-over in this course is synthesized with a text-to-speech model from scripts written and reviewed by the instructor, and the on-screen material (notebooks, code, slides) is the instructor's own work.