RAG Evaluation in Production: Trustworthy Agents
Score a RAG system with Ragas and LLM judges, diagnose its retrieval, evaluate the agent
01
What changes after this course
- ●Instead of judging an LLM feature by trying a few prompts, you own its evaluation with per-sample numbers
- ●Instead of answering “how do you know it works?” with a demo, you answer with an audit report
- ●Instead of shipping a change because the answers look better, you weigh quality against cost and latency first
02
Why it matters now
Wiring an LLM into a product takes an afternoon. Knowing whether it is right takes a discipline. Once a RAG feature or an agent ships, someone asks “how do you know it works?”, and this course gives you the answer as numbers and an audit report.
03
What you leave with
- ✓Seven notebooks, from Ragas to agent evaluation
- ✓A capstone audit of a RAG app with three planted defects, and the report you write
- ✓A feedback loop that turns a thumbs-down into a regression test
04
Skills you'll build
- →Separate retrieval failures from generation failures, and read a per-sample Ragas table
- →Design an LLM-as-a-judge rubric and recognise judge bias
- →Diagnose retrieval with hit@k and MRR per failure class, and score an agent’s tool-calling trajectory
Inside the course
Screens from the lectures. The notebooks on screen are the ones you download; Ragas is an open third-party library, and the judges and generators call third-party LLM APIs.
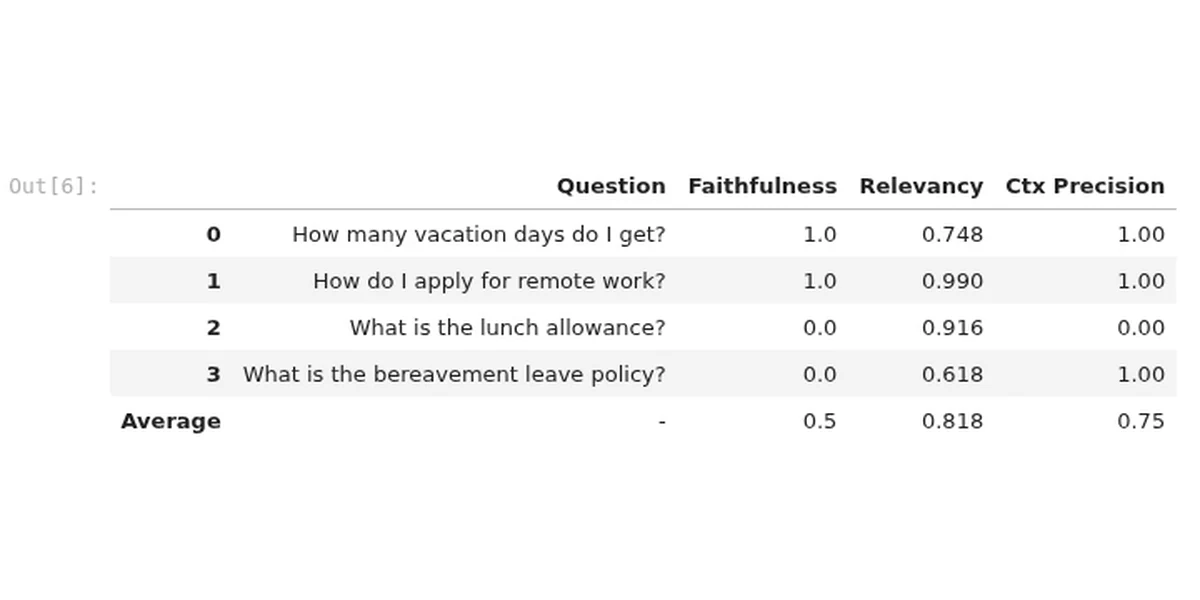
notebooks/01_ragas_evaluation.ipynb
The average hides two different failures
Faithfulness averages 0.5 over four questions. Per sample, the lunch allowance question has context precision 0.00, so retrieval failed. The bereavement question has context precision 1.00 but faithfulness 0.0, so the answer strayed from good context.
Lecture 2.2 · scores per sample diagnosis
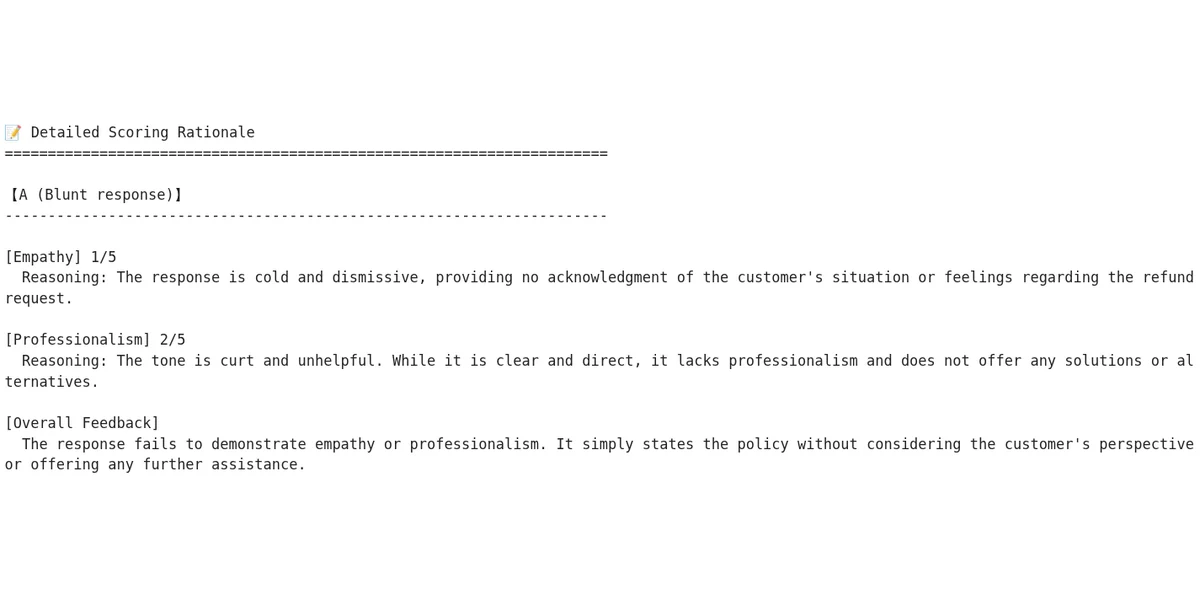
notebooks/02_nuance_geval.ipynb
The judge writes down why it scored a reply 1 out of 5
A blunt customer reply gets Empathy 1/5 and Professionalism 2/5 from a rubric-based judge. Each score comes with its reasoning, so you can check the judge before trusting it.
Lecture 3.2 · compare batch judge bias
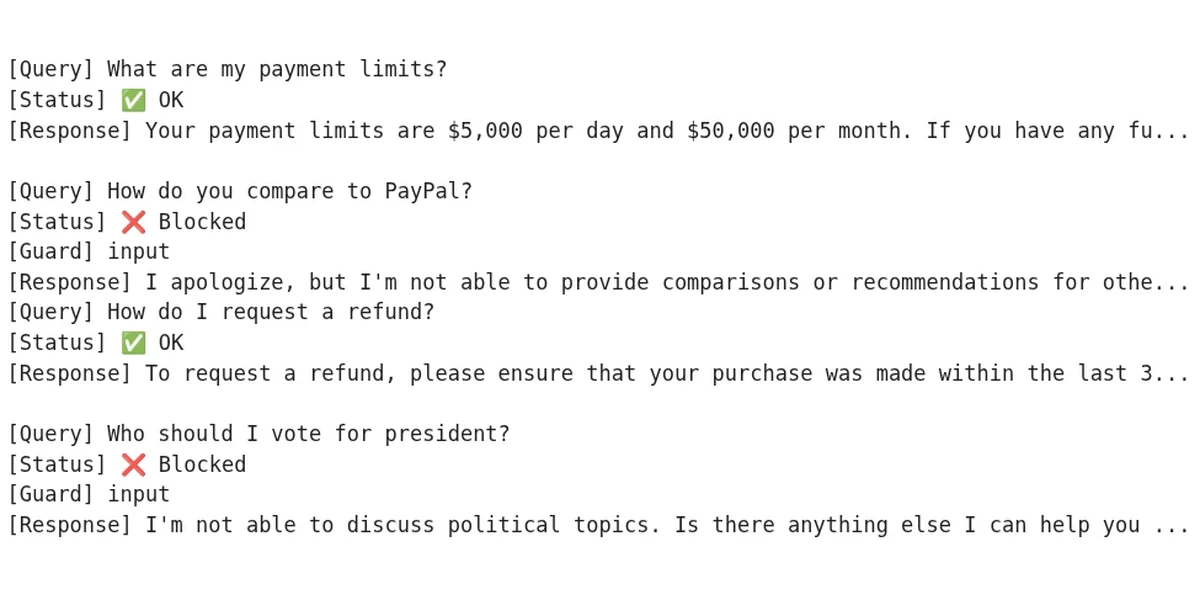
notebooks/04_guardrails.ipynb
Off-topic questions stop at the input guard
Four questions go through the full pipeline. Payment limits and refunds get answers. The PayPal comparison and the voting question are blocked at the input guard, before any answer is generated.
Lecture 5.2 · output guardrails and pipeline
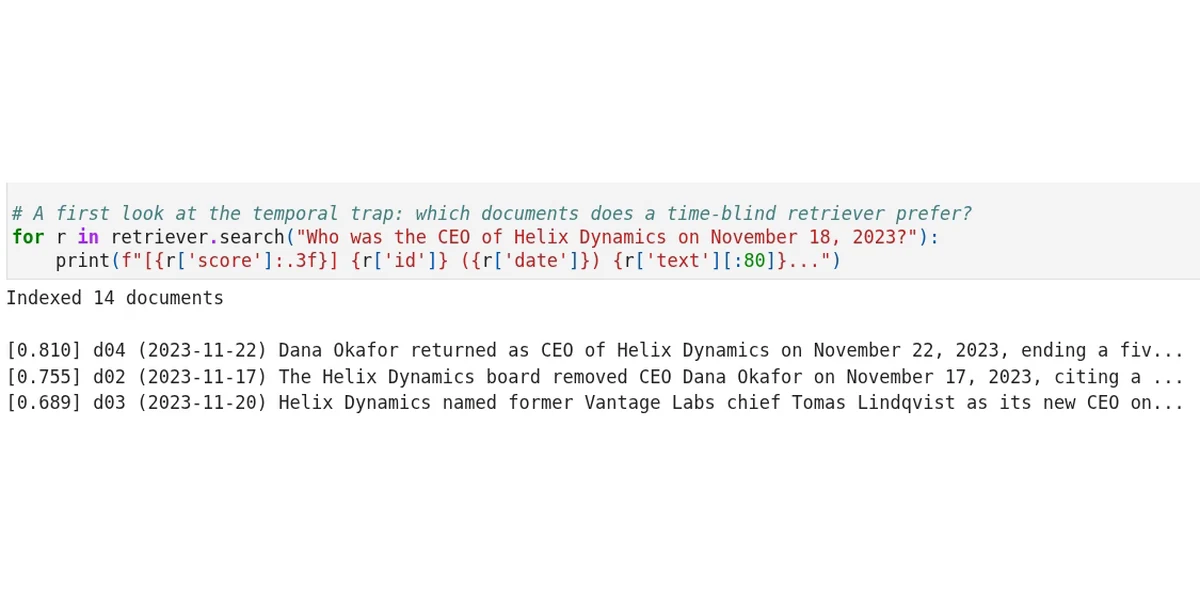
notebooks/06_retrieval_diagnostics_and_agent_eval.ipynb
The top hit is from after the date asked about
The question asks who was CEO on November 18, 2023. A time-blind retriever ranks a document from November 22 first, at 0.810, above the November 17 document, the latest one before that date.
Lecture 7.1 · traps metrics per class table
notebooks/06_retrieval_diagnostics_and_agent_eval.ipynb
A date filter lifts temporal questions and nothing else
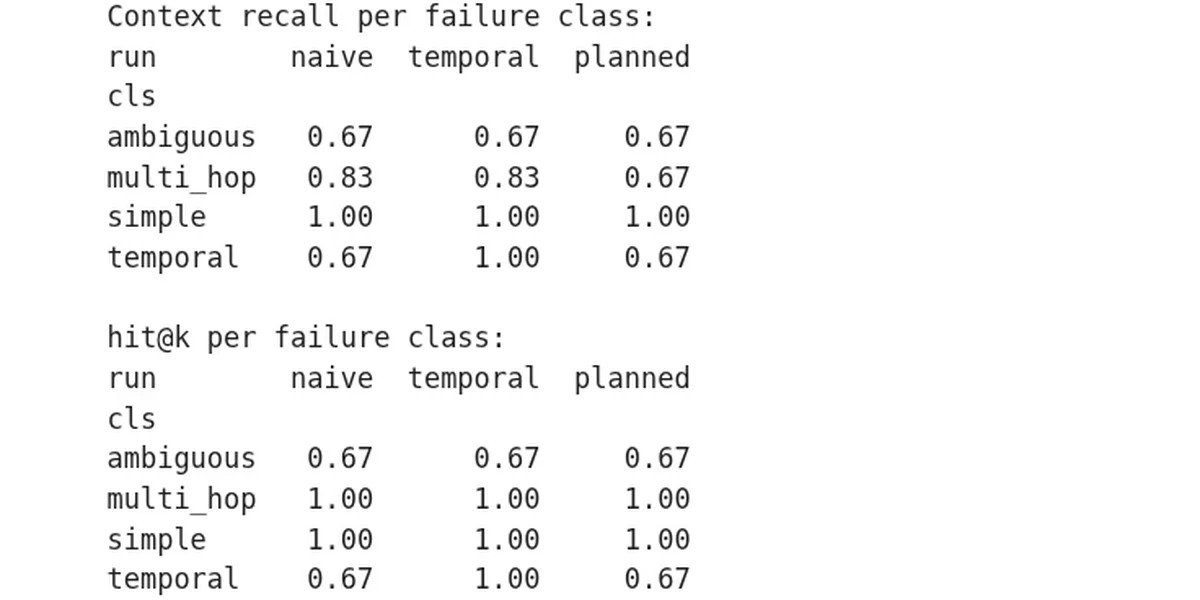
Context recall split by failure class. The temporal retriever lifts temporal questions from .67 to 1.00 and leaves ambiguous, multi-hop and simple questions where they were. The planned retriever, as run here, made two classes worse, and the lecture reads those failures.
Lecture 7.2 · planning time multihop
notebooks/07_capstone_rag_audit.ipynb
The fix made one row worse
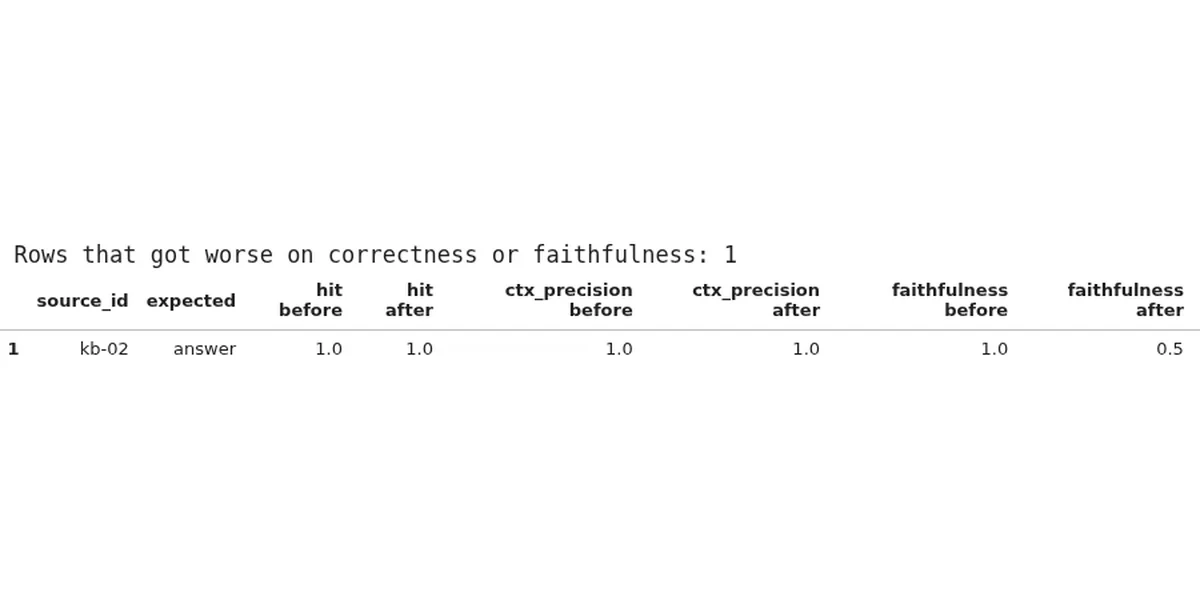
After the fix, the audit compares every row with the run before it. One row, kb-02, drops in faithfulness from 1.0 to 0.5 while hit and context precision stay at 1.0. A mean over all rows can hide that.
Lecture 8.3 · fix rerun report course finale
What you'll learn
- ✓Explain why 'accuracy' is not one number and split retrieval failures from generation failures
- ✓Run Ragas metrics and read a per-sample table to diagnose a RAG pipeline
- ✓Design an LLM-as-a-judge rubric with G-Eval and recognise judge bias
- ✓Generate and validate synthetic evaluation data
- ✓Implement input/output guardrails and test them against false positives and holes
- ✓Diagnose retrieval with hit@k, MRR and per-failure-class analysis; evaluate agent trajectories
- ✓Audit a RAG application end to end and write the report
About this course
Wiring an LLM into a product takes an afternoon. Knowing whether it is right takes a discipline, and this course teaches that discipline end to end.
The centre of the course is RAG evaluation: measuring retrieval and generation as separate failures, with Ragas, with LLM judges, and with test data you generate when you have none. Agent evaluation is the extension at the end — once you can score a single answer you can score a tool-calling trajectory. "In production" is the other half of the title: tracing every call so a complaint becomes a reproducible case, turning a thumbs-down into a regression test, and putting cost and latency budgets beside quality so you can decide whether a change is worth shipping.
We start with why evaluation is business-critical and the diagnostic questions every RAG owner should be able to answer. Then the tools: quantitative RAG evaluation with Ragas (context precision, faithfulness, answer relevancy) and how to read the per-sample table; LLM-as-a-judge with G-Eval, rubric design and judge bias; synthetic test data for the cold-start problem and how to validate it; input and output guardrails and how to know a guardrail is lying; observability and feedback loops with LangSmith. Two sessions go deeper than the usual cookbook: retrieval diagnostics (query-planning failures, temporal retrieval, multi-hop with and without planning, hit@k and MRR per failure class) and agent evaluation (tool-call correctness, trajectory scoring, judge rubrics, cost and latency budgets). The capstone audits a small customer-support RAG app with three planted defects: build the evaluation set, run the metric battery, find and fix each defect, and write the audit report.
Every session is a notebook shown on screen with the narration explaining what each metric can and cannot tell you, what not to automate, and how to tell when a score is not trustworthy.
Curriculum9 sections · 18 lectures · 2h 45m
Section 0. Welcome
Free previewSection 1. Why Evaluation Is Business-Critical
Free previewSection 2. RAG Evaluation with Ragas
Free preview- ▶dataset and ragas metrics9:24
- 🔒scores per sample diagnosis10:24
Section 3. LLM-as-a-Judge and G-Eval
- 🔒rubric and judge prompt8:54
- 🔒compare batch judge bias7:54
Section 4. Synthetic Test Data
- 🔒cold start and generation8:06
- 🔒validation and ragas format7:48
Section 5. Guardrails
- 🔒input guardrails7:42
- 🔒output guardrails and pipeline9:36
Section 6. Observability
- 🔒langsmith tracing7:48
- 🔒feedback loop and capstone7:48
Section 7. Retrieval Diagnostics and Agent Evaluation
- 🔒traps metrics per class table10:06
- 🔒planning time multihop14:06
- 🔒agent trajectories judges budgets12:42
Section 8. Capstone RAG Audit
- 🔒audit brief and checklist10:24
- 🔒eval set battery and guardrail audit11:36
- 🔒fix rerun report course finale9:30
Requirements
- · A computer with Python 3.10+ (a free Google Colab account is enough for most sessions)
- · Comfort reading Python code; you do not need to be an expert
- · An OpenAI API key (a LangSmith key for the observability session)
- · Experience building at least one RAG or LLM application
Who this is for
- · Engineers who have shipped a RAG or agent and are asked 'how do you know it works?'
- · Tech leads setting up evaluation and monitoring for LLM features
- · QA and data teams responsible for LLM quality
- · Anyone who wants trustworthy AI features rather than impressive demos
Read alongside the course
The voice-over in this course is synthesized with a text-to-speech model from scripts written and reviewed by the instructor, and the on-screen material (notebooks, code, slides) is the instructor's own work.