On-Device LLMs Hands-On: Prepare and Compress
Compression theory, choosing a small model and converting it with llama.cpp, MLC LLM and ONNX Runtime
01
What changes after this course
- ●Instead of picking a phone model from a leaderboard, you choose a small model and runtime for a target phone and defend it with numbers
- ●Instead of handing a mobile team a raw checkpoint, you hand them a model that is quantized, converted and ready to integrate
- ●Instead of trusting the licence tag on a model card, you check the licence before the model is distributed
02
Why it matters now
Running a language model on a phone is a chain of choices: which model, how small, which runtime. Each has a measurable consequence, and the licence follows the converted file. In this course’s own materials, a model listed as Apache-2.0 turned out to be for non-commercial use only. This course makes each choice with a benchmark and a licence check.
03
What you leave with
- ✓Six notebooks from hardware to ONNX conversion
- ✓GGUF files at four bit widths with your own benchmarks
- ✓A LICENSES.md with every model checked, including that correction
04
Skills you'll build
- →Estimate tokens per second from hardware specs, because on-device inference is memory-bandwidth-bound
- →Select a small language model with a repeatable framework, including KV-cache size and tokenizer efficiency
- →Quantize to GGUF at four bit widths with benchmarks, compile with MLC LLM and convert to ONNX Runtime with INT4 weights
Inside the course
Screens from the lectures. The notebooks on screen are the ones you download; the tables in them are reference material, not results measured in the video. llama.cpp, MLC LLM and ONNX Runtime are third-party open-source tools.
notebooks/01_ondevice_ai_intro.ipynb
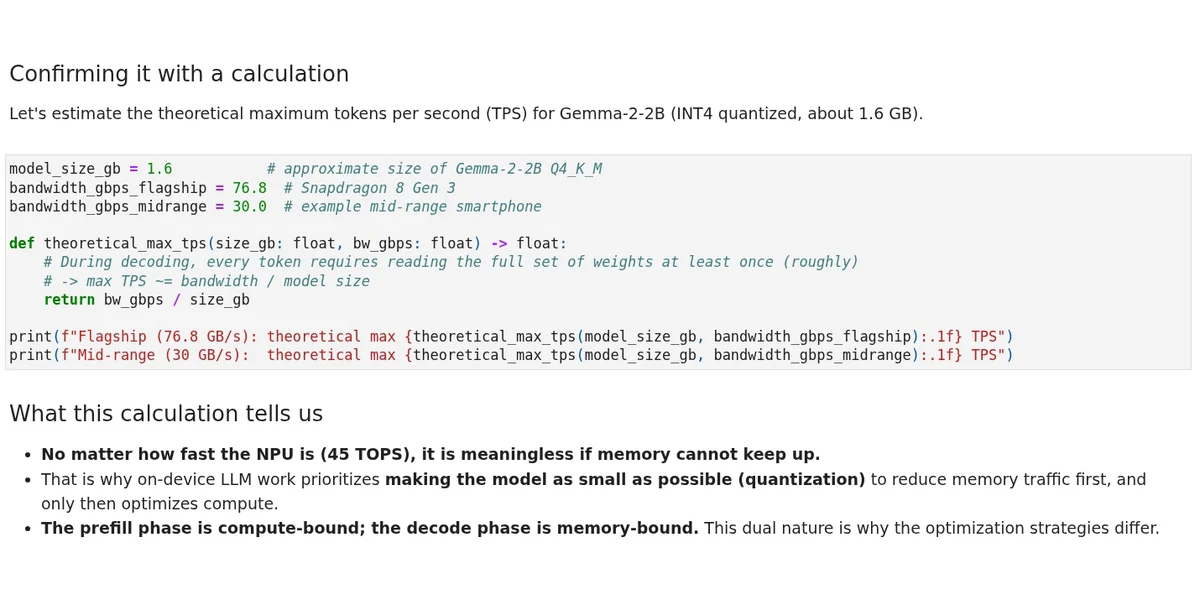
Decode speed is capped by memory bandwidth
Before any tooling, the course puts a ceiling on decode speed: max tokens per second is roughly bandwidth divided by model size. Gemma-2-2B at about 1.6 GB, on a 76.8 GB/s flagship and a 30 GB/s mid-range phone. A 45 TOPS NPU does not help if memory cannot keep up.
▶ Lecture 1.1 · ondevice ai and mobile soc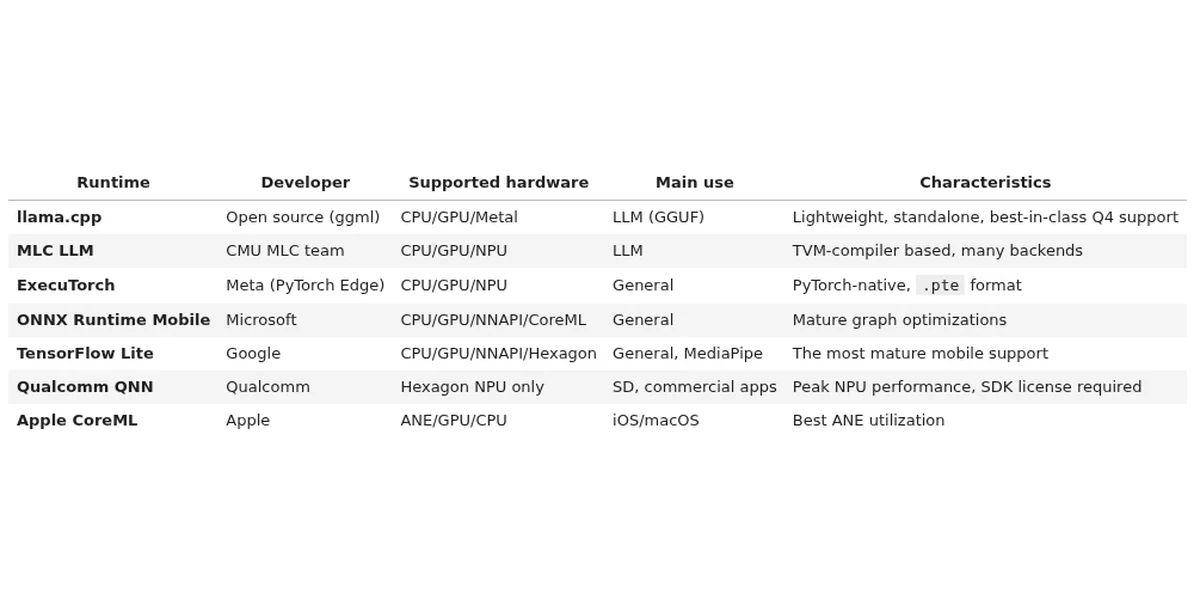
notebooks/01_ondevice_ai_intro.ipynb
Seven on-device runtimes on one page
llama.cpp, MLC LLM, ExecuTorch, ONNX Runtime Mobile, TensorFlow Lite, Qualcomm QNN and Apple CoreML, with the hardware each one targets and what it is used for. You see the landscape before picking a toolchain.
Lecture 1.2 · bandwidth roofline runtimes
notebooks/02_model_compression_theory.ipynb
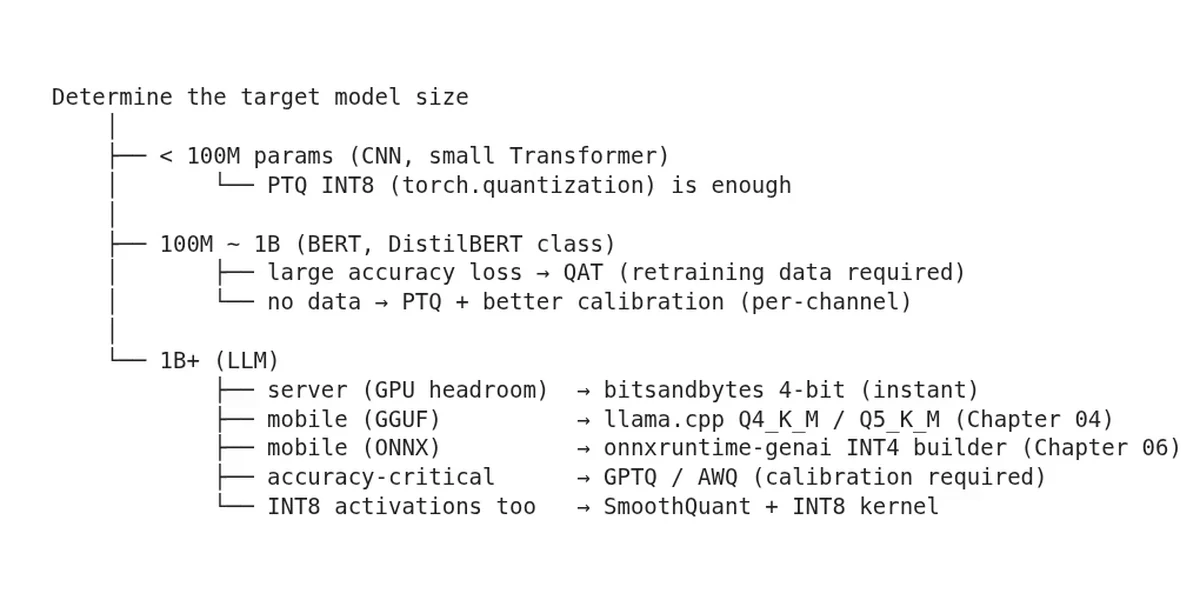
Which technique for which model size
Under 100M parameters, PTQ INT8 is enough. From 100M to 1B, QAT or better per-channel calibration. At 1B and up the target decides: bitsandbytes 4-bit on a server, llama.cpp Q4_K_M or Q5_K_M on mobile, GPTQ or AWQ when accuracy is critical.
Lecture 2.3 · llm quantization and decision tree
notebooks/03_slm_overview.ipynb
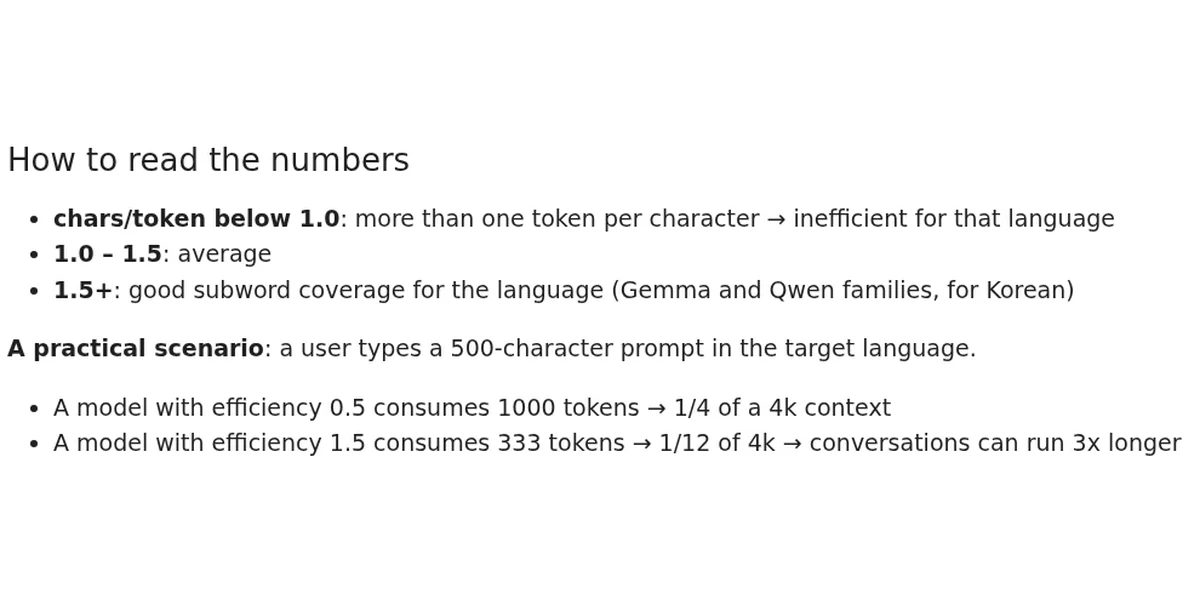
Tokenizer efficiency sets your real context
Characters per token decide how far a context window goes in your users' language. A 500-character prompt costs 1000 tokens at 0.5 characters per token, a quarter of a 4k context, and 333 tokens at 1.5.
Lecture 3.2 · kv cache and tokenizer efficiency
notebooks/03_slm_overview.ipynb
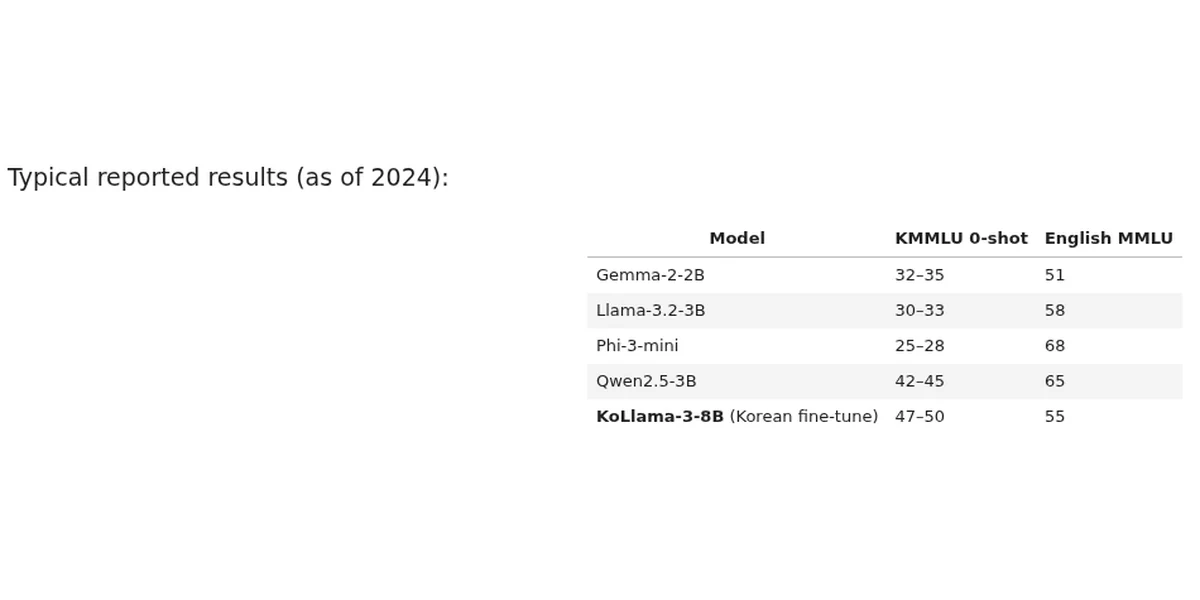
English MMLU can pick the wrong model
Reported results as of 2024, kept as a reference table. Phi-3-mini has the highest English MMLU here (68) and the lowest Korean KMMLU (25-28), so ranking on English alone would pick the wrong model for a Korean app.
Lecture 3.3 · language benchmarks and selection framework
notebooks/04_llama_cpp_gguf_quantization.ipynb
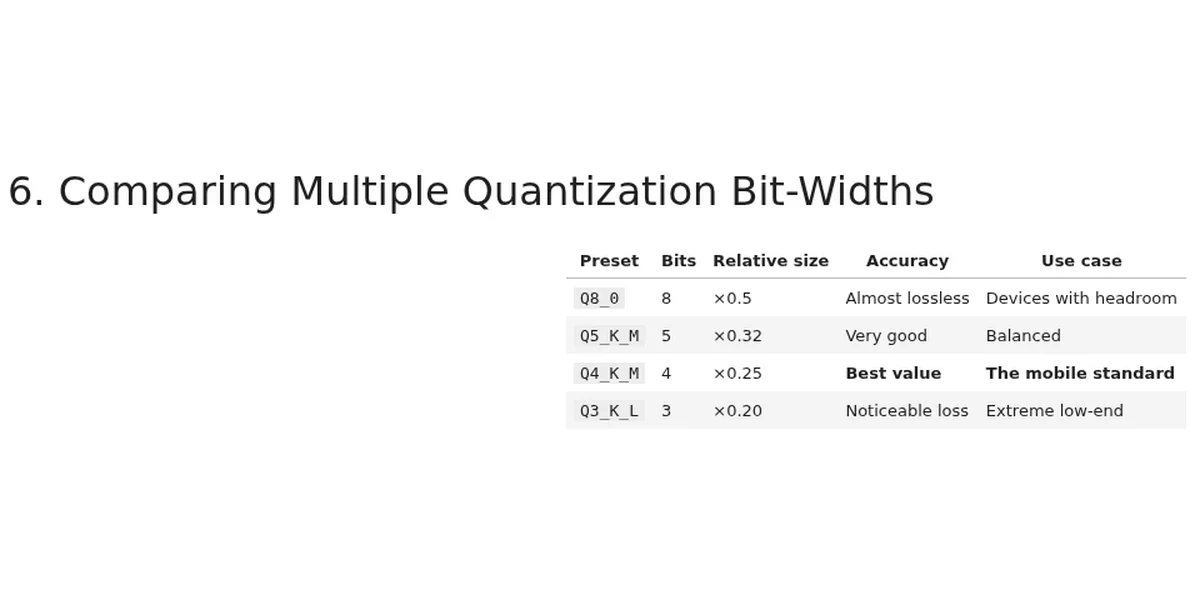
Four GGUF presets and when to use each
Q8_0, Q5_K_M, Q4_K_M and Q3_K_L, from 8 bits down to 3, and from ×0.5 down to ×0.20 relative size. Q4_K_M is marked as the mobile standard; Q3_K_L as noticeable loss for extreme low-end devices.
Lecture 4.2 · download convert quantize and bench
notebooks/05_mlc_llm_compilation.ipynb
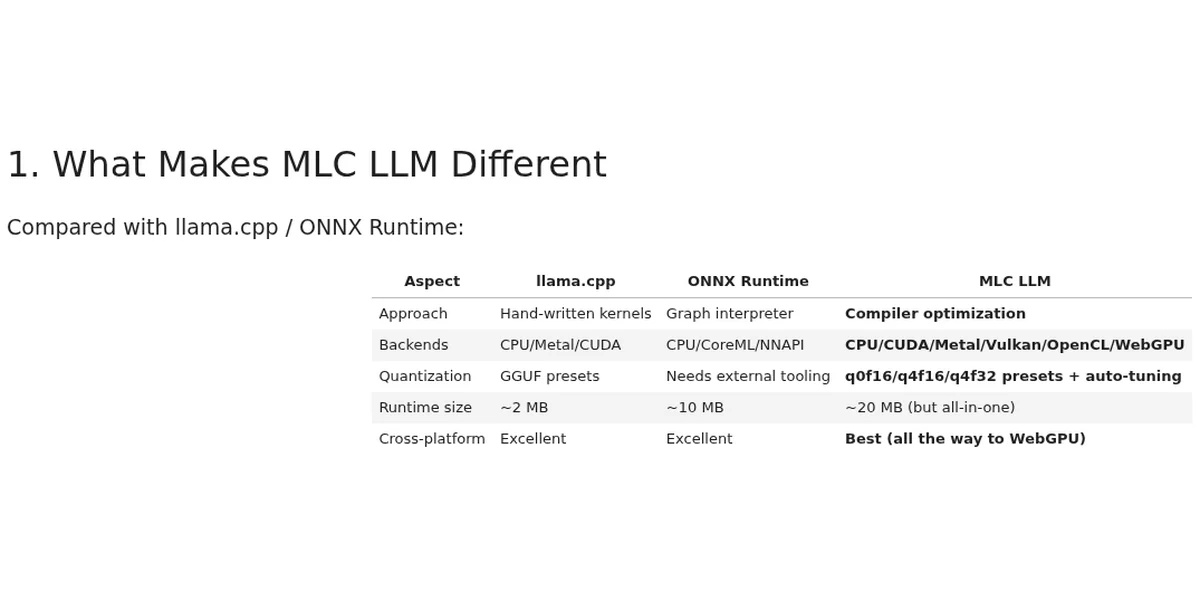
MLC LLM next to llama.cpp and ONNX Runtime
MLC LLM compiles the model instead of using hand-written kernels or a graph interpreter, and reaches Vulkan, OpenCL and WebGPU. The cost is a larger runtime: about 20 MB, against about 2 MB for llama.cpp.
Lecture 5.1 · mlc difference install convert
notebooks/06_onnx_llm_conversion.ipynb
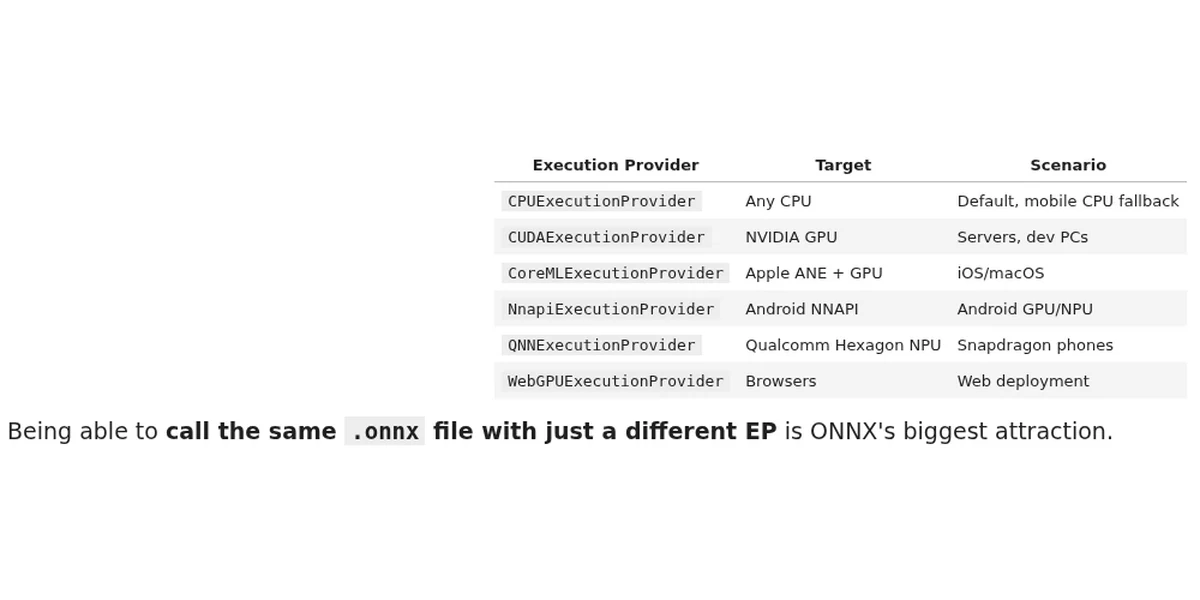
One .onnx file, six execution providers
The notebook's point: the same .onnx file is called with a different execution provider for a CPU, an NVIDIA GPU, Apple ANE through CoreML, Android NNAPI, the Qualcomm Hexagon NPU or a browser.
Lecture 6.2 · int4 woq inference execution providers
What you'll learn
- ✓Explain why on-device inference is memory-bandwidth-bound and estimate tokens per second from hardware specs
- ✓Apply the quantization formula and choose between PTQ, QAT, pruning and distillation
- ✓Select a small language model with a repeatable framework, including KV-cache sizing and tokenizer efficiency
- ✓Build llama.cpp, convert to GGUF and compare bit widths with real benchmarks
- ✓Compile a model with MLC LLM and convert one to ONNX Runtime with INT4 weights
About this course
Before a language model can run on a phone it has to be chosen, shrunk and converted — and every one of those decisions has a measurable consequence. This course is the model half of on-device AI.
We start with the hardware: what is inside a mobile SoC, why memory bandwidth rather than compute is the wall, and how the Roofline model tells you which optimisations will matter. Then compression theory: the quantization formula, post-training quantization versus quantization-aware training, pruning, distillation, and the modern LLM methods (GPTQ, AWQ, SmoothQuant, bitsandbytes) with a decision tree for choosing among them. Then the practical path: selecting a small language model with a repeatable framework (memory budget, KV cache, tokenizer efficiency for your target language, benchmarks), building llama.cpp and quantizing to GGUF at four bit widths with benchmarks, compiling with MLC LLM for a mobile GPU, and converting with Hugging Face Optimum to ONNX Runtime with INT4 weight-only quantization.
Every session is a notebook shown on screen while the narration explains what each command does and what the output means. The follow-up course, *Ship an LLM in an Android App*, takes the model you build here into Kotlin and React Native apps.
**Licensing.** Converting a model to GGUF, MLC or ONNX creates a derivative work that inherits the original licence, so this course ships a `Resources/LICENSES.md` with every model checked against its actual licence text — including one correction to the notebooks: **`Qwen2.5-3B-Instruct` is under the Qwen Research License, "FOR NON-COMMERCIAL PURPOSES ONLY", not Apache-2.0** as session 3's comparison table states. Gemma 2 and Llama 3.2 are commercially usable with notice and attribution duties; Phi-3-mini (MIT) and TinyLlama (Apache-2.0) are the unencumbered options.
Curriculum7 sections · 19 lectures · 2h 33m
Section 0. Welcome
Free previewSection 1. On-Device AI and Mobile Hardware
Free preview- ▶section 1 intro0:12
- ▶ondevice ai and mobile soc9:00
- 🔒bandwidth roofline runtimes10:24
Section 2. Model Compression Theory
- 🔒quantization formula and ptq10:00
- 🔒qat ste pruning distillation9:36
- 🔒llm quantization and decision tree9:12
Section 3. Small Language Models
- 🔒section 3 intro0:12
- 🔒slm definition and lineup9:30
- 🔒kv cache and tokenizer efficiency9:12
- 🔒language benchmarks and selection framework9:36
Section 4. llama.cpp and GGUF
- 🔒environment token and cmake build9:30
- 🔒download convert quantize and bench8:30
- 🔒size vs speed quality and tuning8:30
Section 5. MLC LLM
- 🔒mlc difference install convert11:54
- 🔒mlc compile artifacts test port8:36
Section 6. ONNX Runtime Conversion
- 🔒why onnx optimum export8:54
- 🔒int4 woq inference execution providers9:12
- 🔒ep benchmark graph speculative app tips9:24
Requirements
- · A computer with Python 3.10+ (a free Google Colab account is enough for most sessions)
- · Comfort reading Python code; you do not need to be an expert
- · A Hugging Face account for model downloads
- · A GPU helps; most notebooks run on CPU or Colab
- · Willingness to read `Resources/LICENSES.md`: several of the models compared here are gated, and Qwen2.5-3B is non-commercial
Who this is for
- · Mobile and ML engineers preparing models for on-device deployment
- · Developers choosing between GGUF, MLC and ONNX Runtime
- · Anyone who wants measured answers about on-device model performance
Read alongside the course
The voice-over in this course is synthesized with a text-to-speech model from scripts written and reviewed by the instructor, and the on-screen material (notebooks, code, slides) is the instructor's own work.