LLM Inference Optimization Part 2 — KV Cache Optimization
KV Cache quantization (int8/int4), PCA compression (KVTC), and PagedAttention (vLLM). Hands-on memory reduction code and scenario-based configuration guide.
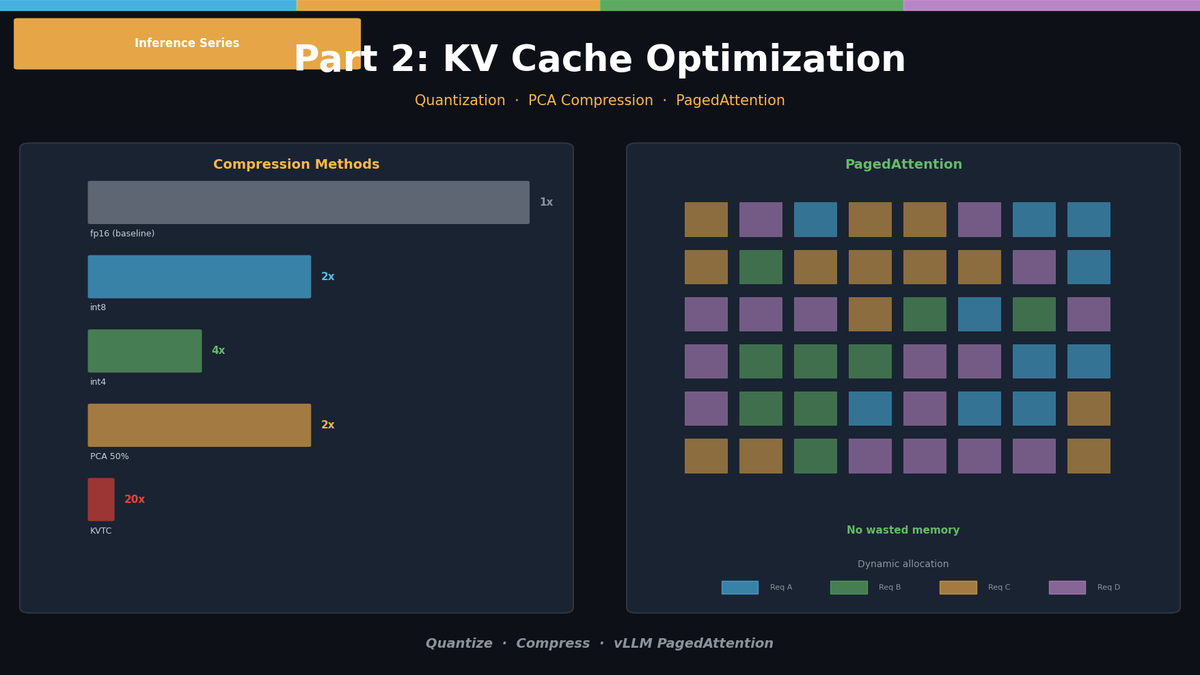
In Part 1, we covered the structure of Attention and how KV Cache works. In this part, we look at practical techniques for optimizing the KV Cache itself, with code.
Even when model weights are reduced through quantization, KV Cache is almost always left in fp16. As context length grows, it is common for KV Cache to consume more than half of total VRAM. We cover three approaches to solving this problem.
1. KV Cache Quantization
How It Works
The rest of this series is paid
- ✓ The whole “LLM inference optimization” series: 3 posts in English, 3 in Korean
- ✓ 3 Jupyter notebooks
- ✓ One payment, no expiry. Opens when you sign in with the email you pay with.
The series pass needs no account to pay. The subscription needs a free account.