Fine-tuning Gemma 4 MoE — Customizing Arena #6 with 3.8B Active Parameters
Apply QLoRA to Gemma 4 26B MoE. Expert layer LoRA strategies, Dense vs MoE comparison, MoE-specific training tips, and Ollama deployment. LoRA Series Part 4.
Fine-tuning Gemma 4 MoE — Customizing Arena #6 with Just 3.8B Active Parameters
Series: Part 1: LoRA Theory | Part 2: QLoRA + Custom Data | Part 3: Eval + Deploy | Part 4 (this post)
Parts 1-3 covered LoRA fundamentals through deployment using Qwen 2.5 7B. Part 4 levels up — we apply LoRA to a Gemma 4 MoE model.
Why Gemma 4? Three reasons:
- MoE architecture: 26B total params, only 3.8B active. Inference cost is 4B-class, but performance is Arena #6
This part is for subscribers
A subscription unlocks every premium series and its Jupyter notebooks.
You need a free account to subscribe. Cancel anytime.
Related Posts
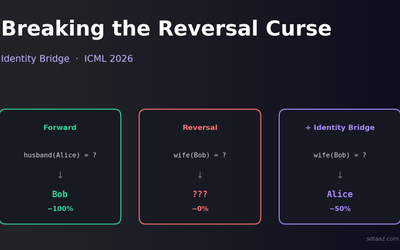
Breaking the Reversal Curse with Identity Bridges — the ICML 2026 fix that shouldn't work but does
LLMs trained on "Alice's husband is Bob" famously fail on "Bob's wife is?" — the reversal curse. A new ICML 2026 paper fixes it by adding one weird kind of self-referential example to the training set. The naive version doesn't work; the right version does.

Qwen 3.5 Local Installation & Setup Guide — From Ollama to vLLM
Step-by-step guide to running Qwen 3.5 locally. From 5-minute Ollama setup to production vLLM servers, plus optimal model size selection per GPU.
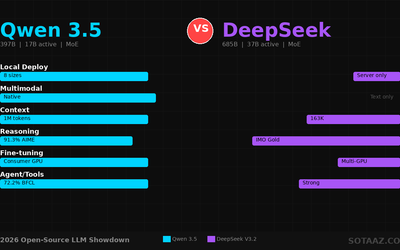
Qwen 3.5 vs DeepSeek V3.2 — The 2026 Open-Source LLM Showdown
Complete comparison of Qwen 3.5 and DeepSeek V3.2: architecture, benchmarks, hardware requirements, and practical recommendations.